LSM-Tree vs. B+Tree Storage Engine Architecture: Write Amplification, Compaction, and NVMe I/O Alignment
A deep-dive database internals analysis comparing Log-Structured Merge-Tree (LSM-Tree) and B+Tree storage engines, examining Write Amplification Factors (WAF), MemTable/SSTable compaction strategies, Bloom filters, and flash block wear leveling on NVMe SSDs.
Written by: TrendSpike Editorial Desk | Published: October 16, 2026 | Domain: Database Internals & Storage Systems
At the core of every relational and distributed database lies the storage engine—the subsystem responsible for translating logical transactions into physical block allocations on non-volatile media. While traditional relational databases (such as PostgreSQL, MySQL InnoDB, and Oracle) rely on read-optimized, in-place update B+Tree structures, high-ingestion distributed databases (such as RocksDB, Apache Cassandra, ScyllaDB, and CockroachDB) utilize append-only Log-Structured Merge-Trees (LSM-Trees). Selecting and tuning these engines requires navigating the fundamental trade-off known as the RUM Conjecture: optimizing simultaneously for Read Overhead, Update (Write) Overhead, and Memory/Storage Space Overhead.
1. B+Tree Architecture: In-Place Page Updates and Random I/O
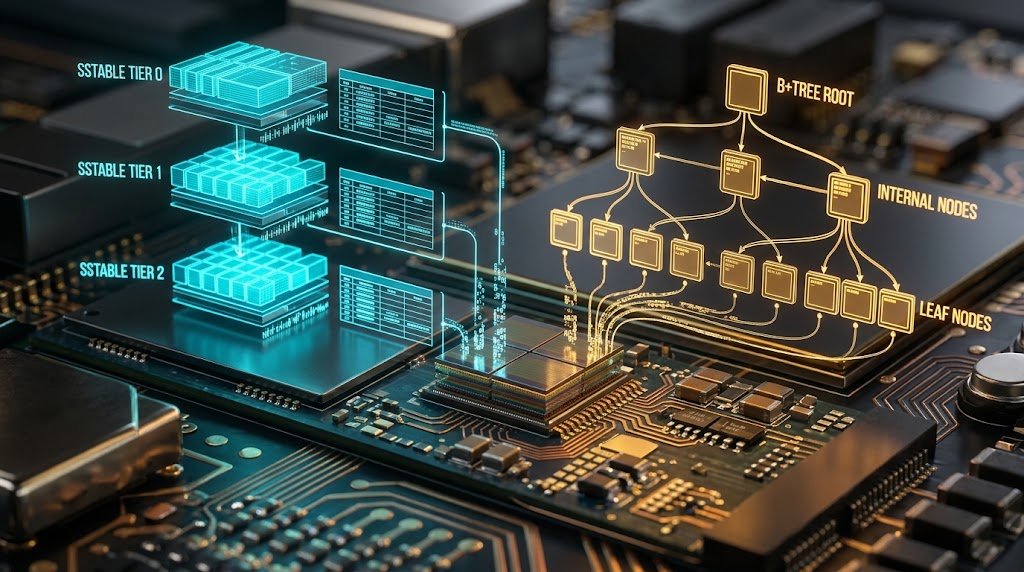
A B+Tree organizes data into fixed-size pages (typically 8 KB in PostgreSQL or 16 KB in InnoDB) arranged in a balanced, multi-level hierarchy of internal routing nodes and doubly linked leaf pages:
- Point and Range Read Efficiency: Because every key exists in exactly one canonical leaf page and leaf nodes maintain sequential sibling pointers, a B+Tree guarantees $O(\log_B N)$ point lookups and contiguous range scans with minimal read amplification.
- High Write Amplification (WAF): Updating a single 100-byte row inside a 16 KB B+Tree leaf page requires modifying the buffered page in memory, writing a Write-Ahead Log (WAL) record (and an additional doublewrite buffer write in InnoDB to prevent torn pages), and eventually flushing the entire 16 KB page to disk. Modifying 100 bytes thus triggers 16,384 bytes of physical NAND flash writes—creating severe random write I/O and accelerating SSD Flash Translation Layer (FTL) garbage collection.
2. LSM-Tree Architecture: Append-Only Sequential Ingestion
To eliminate random disk writes, an LSM-Tree converts all mutations (inserts, updates, and deletes) into sequential append operations across three architectural tiers:
- Write-Ahead Log (WAL): Incoming writes are appended sequentially to an on-disk WAL for crash recovery using `fsync` or `fdatasync`.
- MemTable (In-Memory SkipList): Simultaneously, the mutation is inserted into a sorted in-memory structure (typically a lock-free concurrent
SkipListorVectorRep). Deletes do not remove data immediately; instead, they append a special marker called a Tombstone. - Immutable SSTables (Sorted String Tables): Once a MemTable reaches its capacity threshold (e.g., 64 MB), it is frozen into an immutable MemTable and flushed sequentially to disk as a Level 0 (L0) SSTable, composed of sorted data blocks, an index block, and a metadata footer.
3. Compaction Strategies: Size-Tiered (STCS) vs. Leveled (LCS)
Because LSM-Trees never overwrite existing SSTables in place, obsolete versions of keys and uncollected tombstones accumulate across multiple disk files, degrading read performance and inflating disk usage. Background Compaction threads merge-sort SSTables to purge overwritten keys and tombstones:
- Size-Tiered Compaction (STCS): Used by default in write-heavy workloads (e.g., Cassandra). When multiple SSTables of similar size accumulate, they are merged into a single larger SSTable. STCS minimizes Write Amplification (WAF ≈ 4–8) but suffers from severe Space Amplification, temporarily requiring up to 50% free disk capacity to merge the largest SSTable tier.
- Leveled Compaction (LCS): Used in RocksDB and LevelDB. Disk storage is partitioned into exponentially growing levels ($L_1 = 10\text{ MB}, L_2 = 100\text{ MB}, L_3 = 1\text{ GB}$). Within any level $L_i$ ($i \ge 1$), key ranges across SSTables are strictly non-overlapping. LCS keeps space amplification below 10%–15% and bounds point-lookup latency, at the cost of higher Write Amplification (WAF ≈ 10–30).
4. Architectural Trade-Off Matrix: B+Tree vs. LSM-Tree
| Performance Dimension | B+Tree (InnoDB / PostgreSQL) | LSM-Tree (RocksDB / ScyllaDB) |
|---|---|---|
| Write I/O Pattern | Random in-place page rewrites (8KB–16KB). | 100% sequential append-only SSTable flushes. |
| Write Amplification (WAF) | High on small random updates (page dirtying). | Low during ingestion; deferred to background compaction. |
| Read Amplification | Minimal (1 canonical leaf page per key). | Higher (must check MemTable + L0–Ln SSTables; mitigated via Bloom filters). |
| Space Utilization | 25%–35% internal page fragmentation from node splits. | Tightly packed immutable blocks + ZSTD/LZ4 block compression. |
5. Mitigating LSM Read Amplification: Bloom Filters and Prefix Seek
Because a point lookup in an LSM-Tree could theoretically require binary-searching L0 files plus one file per level ($L_1 \dots L_k$), production engines embed a bit-array Bloom Filter inside each SSTable’s filter block (typically configured at 10 bits per key, yielding a <1% false-positive rate). Before issuing an NVMe disk read for an SSTable data block, the engine hashes the target key against the in-memory Bloom filter; if the filter returns negative, the entire SSTable level is bypassed in nanoseconds, reducing average point-lookup disk I/O to a single read.
Official Engineering Specifications & Systems Research
- • Meta Engineering / RocksDB Documentation: GitHub.com/facebook/rocksdb — RocksDB Architecture, Leveled Compaction & SSTable Format
- • PostgreSQL Global Development Group: PostgreSQL.org — Chapter 64: B-Tree Index Implementation & Page Layout Internals
- • ACM SIGMOD / Harvard DASlab Research: ACM Digital Library — Designing Access Methods: The RUM Conjecture (Read, Update, Memory Trade-offs)
- • USENIX Association (FAST Conference): USENIX.org — Optimizing Space Amplification in RocksDB on Flash Storage
TrendSpike Editorial Team
Staff Research & Technical AnalysisIndependent research covering distributed cloud systems, modern enterprise software engineering, and macro-financial policy. Our technical and financial analyses reference primary documentation, official regulatory filings, and benchmark architectures.