Optimizing PostgreSQL B-Tree Indexes: Deduplication, Page Splits, and Scalar Array Scans
An engineering guide to PostgreSQL B-Tree internals, covering page splits, bottom-up index deletion, deduplication, fillfactor tuning, and query planning for high-write workloads.
Written by: TrendSpike Engineering Desk | Published: October 8, 2026 | Engine: PostgreSQL 16 / 17 / 18 B-Tree Architecture
PostgreSQL B-Tree indexes are the default index type for many relational workloads because they support equality and range searches over data with a defined ordering. Their performance, however, depends on how index pages fill, how frequently indexed values change, how many duplicate keys exist, and how the query planner can use the index. For large write-heavy tables, understanding page splits, bottom-up index deletion, deduplication, and fillfactor can help database engineers make more informed indexing decisions.
1. B-Tree Page Structure and the Cost of Page Splits
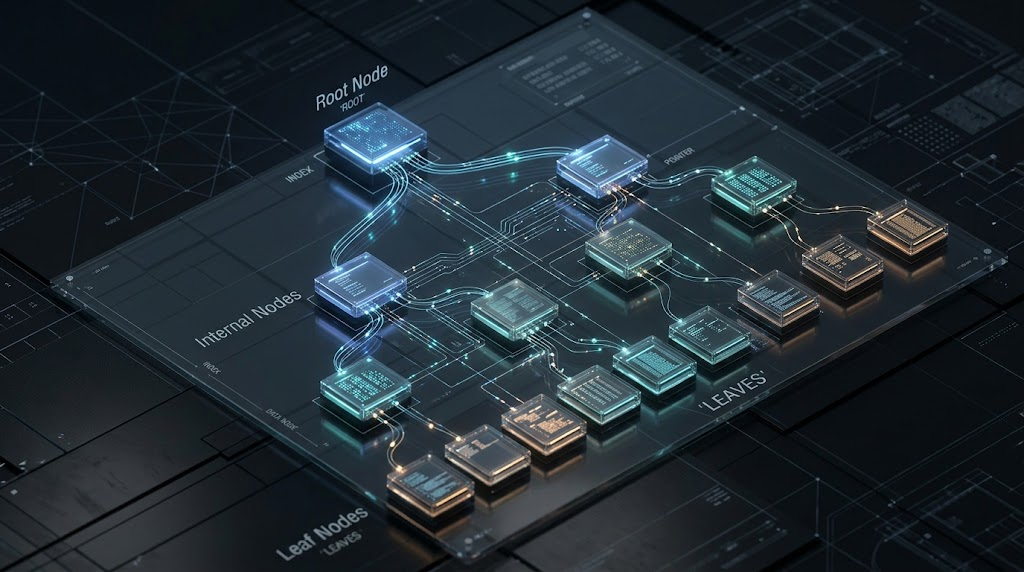
PostgreSQL B-Tree indexes are multi-way balanced trees stored across database pages. A standard PostgreSQL page is 8KB, and B-Tree leaf pages contain index tuples that point to rows in the underlying table.
When an index page does not have enough room for an incoming index tuple, PostgreSQL can perform a page split:
- A new leaf page is created to make room for additional index tuples.
- A portion of the existing items is moved to the new page.
- The parent page receives a new downlink describing the additional child page.
- If the parent also becomes full, the split can propagate upward through the tree.
Page splits are a normal part of B-Tree operation, but frequent splits can increase index growth and modify the physical structure of the index. Workloads involving frequent inserts or updates therefore require careful consideration of index fillfactor and access patterns.
2. Fillfactor: Creating Space for Future Writes
PostgreSQL allows B-Tree indexes to specify a fillfactor storage parameter. The default B-Tree fillfactor is 90, meaning PostgreSQL does not initially attempt to pack every leaf page completely full.
For write-heavy workloads, deliberately leaving additional free space can reduce the pressure that would otherwise lead to early page splits. PostgreSQL documentation notes that values in the 50–90 range can be useful in some workloads, although the appropriate setting remains workload-dependent.
- Default behavior: B-Tree indexes use a default fillfactor of 90.
- Write-heavy workloads: A lower value can provide additional room for future inserts and updates.
- Static tables: A fillfactor of 100 can maximize initial space utilization when the table is genuinely static.
- Do not tune blindly: Lower fillfactor consumes more physical space, so it should be evaluated against actual write and read behavior.
For example, an index that receives frequent updates may benefit from additional free space, while an index on a table that is loaded once and rarely modified may prioritize compact storage instead.
3. B-Tree Deduplication for Repeated Values
PostgreSQL B-Tree indexes can use deduplication to store repeated indexed values more efficiently. The technique is particularly relevant to non-unique indexes where the same key value occurs across many table rows.
Instead of storing the complete key value repeatedly, PostgreSQL can represent duplicate entries using a posting-list structure containing the shared key and a sorted collection of table tuple identifiers (TIDs).
- Repeated values: Multiple rows with the same indexed key can be represented more compactly.
- Index size: Deduplication can significantly reduce storage requirements when duplicate values are common.
- Read efficiency: PostgreSQL documentation notes that deduplication can also improve query latency and overall throughput in appropriate indexes.
- Default behavior: B-Tree deduplication is enabled by default through the
deduplicate_itemsstorage parameter.
Deduplication is not universally applicable. PostgreSQL has implementation restrictions for certain data types, collations, container types, and indexes containing INCLUDE columns. Database engineers should therefore verify whether an individual index can safely use the optimization.
4. Bottom-Up Index Deletion and Update-Heavy Tables
Index maintenance becomes especially important under PostgreSQL's MVCC model. An UPDATE can create a new row version, and indexes may need corresponding physical index tuples even when the indexed value itself has not logically changed.
PostgreSQL uses bottom-up index deletion to remove obsolete index tuples associated with version churn in certain update-heavy workloads. The mechanism operates locally on B-Tree leaf pages and can sometimes remove obsolete entries before a page split becomes necessary.
- Version churn: Repeated updates can create obsolete index entries.
- Local cleanup: Bottom-up deletion can remove obsolete entries from affected leaf pages.
- Reduced split pressure: Freeing space can allow an incoming tuple to fit without immediately splitting the page.
- Interaction with fillfactor: Available free space can influence how effectively the index accommodates additional tuple versions.
This mechanism complements ordinary table and index maintenance performed by PostgreSQL's vacuum processes. It should not be treated as a replacement for appropriate database maintenance.
5. Scalar Array Searches and the Query Planner
B-Tree indexes are commonly used for equality and range predicates, but PostgreSQL can also use B-Tree indexes for constructs equivalent to combinations of equality conditions, including IN expressions.
For example, a query such as:
SELECT * FROM orders WHERE customer_id IN (101, 205, 309);can be evaluated using an appropriate B-Tree index on customer_id. Internally, PostgreSQL supports scalar-array operations such as = ANY (array), allowing the planner to consider index-assisted execution where appropriate.
However, the presence of an index does not guarantee that PostgreSQL will use it. The planner considers estimated selectivity, table size, available statistics, cost settings, and the expected amount of data that must be retrieved.
6. Choosing Index Settings for Production Workloads
There is no universal B-Tree configuration that is optimal for every PostgreSQL workload. Index tuning should begin with the access pattern and workload characteristics rather than a fixed percentage or page-size target.
- Read-heavy and mostly static tables: Standard fillfactor settings may be sufficient, with higher packing potentially reducing physical size.
- Write-heavy tables: Test whether a lower fillfactor reduces page-split pressure and improves sustained write behavior.
- Low-cardinality indexed columns: Deduplication can be particularly relevant when many rows share the same indexed value.
- Frequently updated rows: Examine index growth and version churn rather than assuming that every update creates the same maintenance cost.
- Large
INor array predicates: UseEXPLAINandEXPLAIN ANALYZEto determine whether the planner can use the available index efficiently.
7. How to Diagnose B-Tree Performance
Index optimization should be measured rather than assumed. PostgreSQL provides several tools for examining query plans and index behavior.
EXPLAIN: Shows the planner's chosen execution strategy.EXPLAIN ANALYZE: Executes the query and reports actual execution statistics.pg_stat_user_indexes: Provides statistics that can help identify index usage patterns.pgstattupleextension: Provides additional information for examining table and index physical characteristics.
A useful tuning workflow is to establish a baseline, change one index parameter or structural property, and then compare execution time, buffer activity, index size, write behavior, and workload throughput.
8. When to Consider REINDEX
REINDEX rebuilds an index and can be useful when an index needs to be reconstructed. However, rebuilding an index should not be treated as a routine solution for every performance problem.
Before rebuilding an index, database administrators should identify why the index is consuming excessive space or performing poorly. The underlying issue may instead involve query design, statistics, table growth, update patterns, or an unsuitable index definition.
For production systems where concurrent access must continue, PostgreSQL also provides REINDEX CONCURRENTLY, subject to its operational requirements and trade-offs.
9. Practical B-Tree Optimization Checklist
- Identify the actual queries that need index support.
- Use
EXPLAINandEXPLAIN ANALYZEbefore changing index design. - Monitor index usage and physical growth over time.
- Consider lower fillfactor values for appropriate write-heavy workloads.
- Keep B-Tree deduplication enabled unless a documented workload-specific reason exists to disable it.
- Pay particular attention to update-heavy tables and index version churn.
- Do not assume that every
INquery will use an index; verify the execution plan. - Do not rebuild indexes simply because they are large; identify the underlying cause first.
10. Engineering Takeaway
PostgreSQL B-Tree performance is not determined by a single tuning switch. Page splits, fillfactor, duplicate-key distribution, MVCC version churn, and query-planner decisions all interact with the workload.
The most reliable optimization strategy is therefore measurement-driven: inspect the execution plan, understand how the index is being modified, monitor physical growth, and tune settings according to the workload rather than applying fixed performance rules.
Sources & Official References
- PostgreSQL Documentation — B-Tree Indexes
- PostgreSQL Documentation — CREATE INDEX
- PostgreSQL Documentation — Indexes
- PostgreSQL Documentation — Monitoring Database Activity
Disclaimer: This article is provided for general technical and educational purposes. PostgreSQL behavior and available features can vary by version, configuration, data distribution, and workload. Production changes should be tested against representative workloads before deployment.
TrendSpike Editorial Team
Staff Research & Technical AnalysisIndependent research covering distributed cloud systems, modern enterprise software engineering, and macro-financial policy. Our technical and financial analyses reference primary documentation, official regulatory filings, and benchmark architectures.